What it is for
An agent that works pull requests and needs one bounded next step chosen before it touches anything, with the merge decision kept outside the agent.
Evaluate selects one step from the eligible candidates you submit, or refuses, and returns an auditable trace. Your agent performs the selected step if your own rules allow it. A selection is never permission or authority. Anything with an outside effect needs its own separate yes from the owner, outside Evaluate.
How support scores are set
Each candidate carries operator_reported_support, a number from 0 to 1 that you report. Evaluate does not verify it. This skill's basis: Labeled judgment first. The sample scenario's values are illustrative placeholders, not measurements.
- Labeled judgment is the starting point. Most teams have no history of which agent step helped on which kind of pull request. Report your own judgment for each candidate and say so in its description. The sample's own values are labeled illustrative; replace them.
- Measured data when you have it. If you log what happened after each step (for example, how often the step led to a fixed check or an accepted review comment), use that dated, sourced rate as the support value and name the window in the description. Do not use the agent's own confidence.
- Facts in
contextsuch as the check status are reported by you. Evaluate does not verify them.
What Evaluate returns
| Field | Meaning |
|---|---|
result.outcome | selected or governed_noop_refusal |
result.selected_candidate_id | One of your submitted review candidates, or null on a refusal |
result.reason_codes | Bounded outcome codes, for example candidate_selected_within_bounded_evaluation on a selection. This field names the outcome category. It is not a reason for or against any single candidate, and neither are the entries in trace.lambda_decisions. |
result.trace | Request digests, the recorded gate entries (gate_id, disposition, reason_code), trace_id, and the commit time |
result.authority and trace flags | Five authority flags and four trace flags, all false. Check them. |
receipt_id | Your account's record of this evaluation |
result.commercial_receipt.receipt_id | The evaluator's receipt. A different record from receipt_id; keep both. |
A governed refusal returns no selection. Stop that path and use the fallback you declared in advance.
Sample receipt
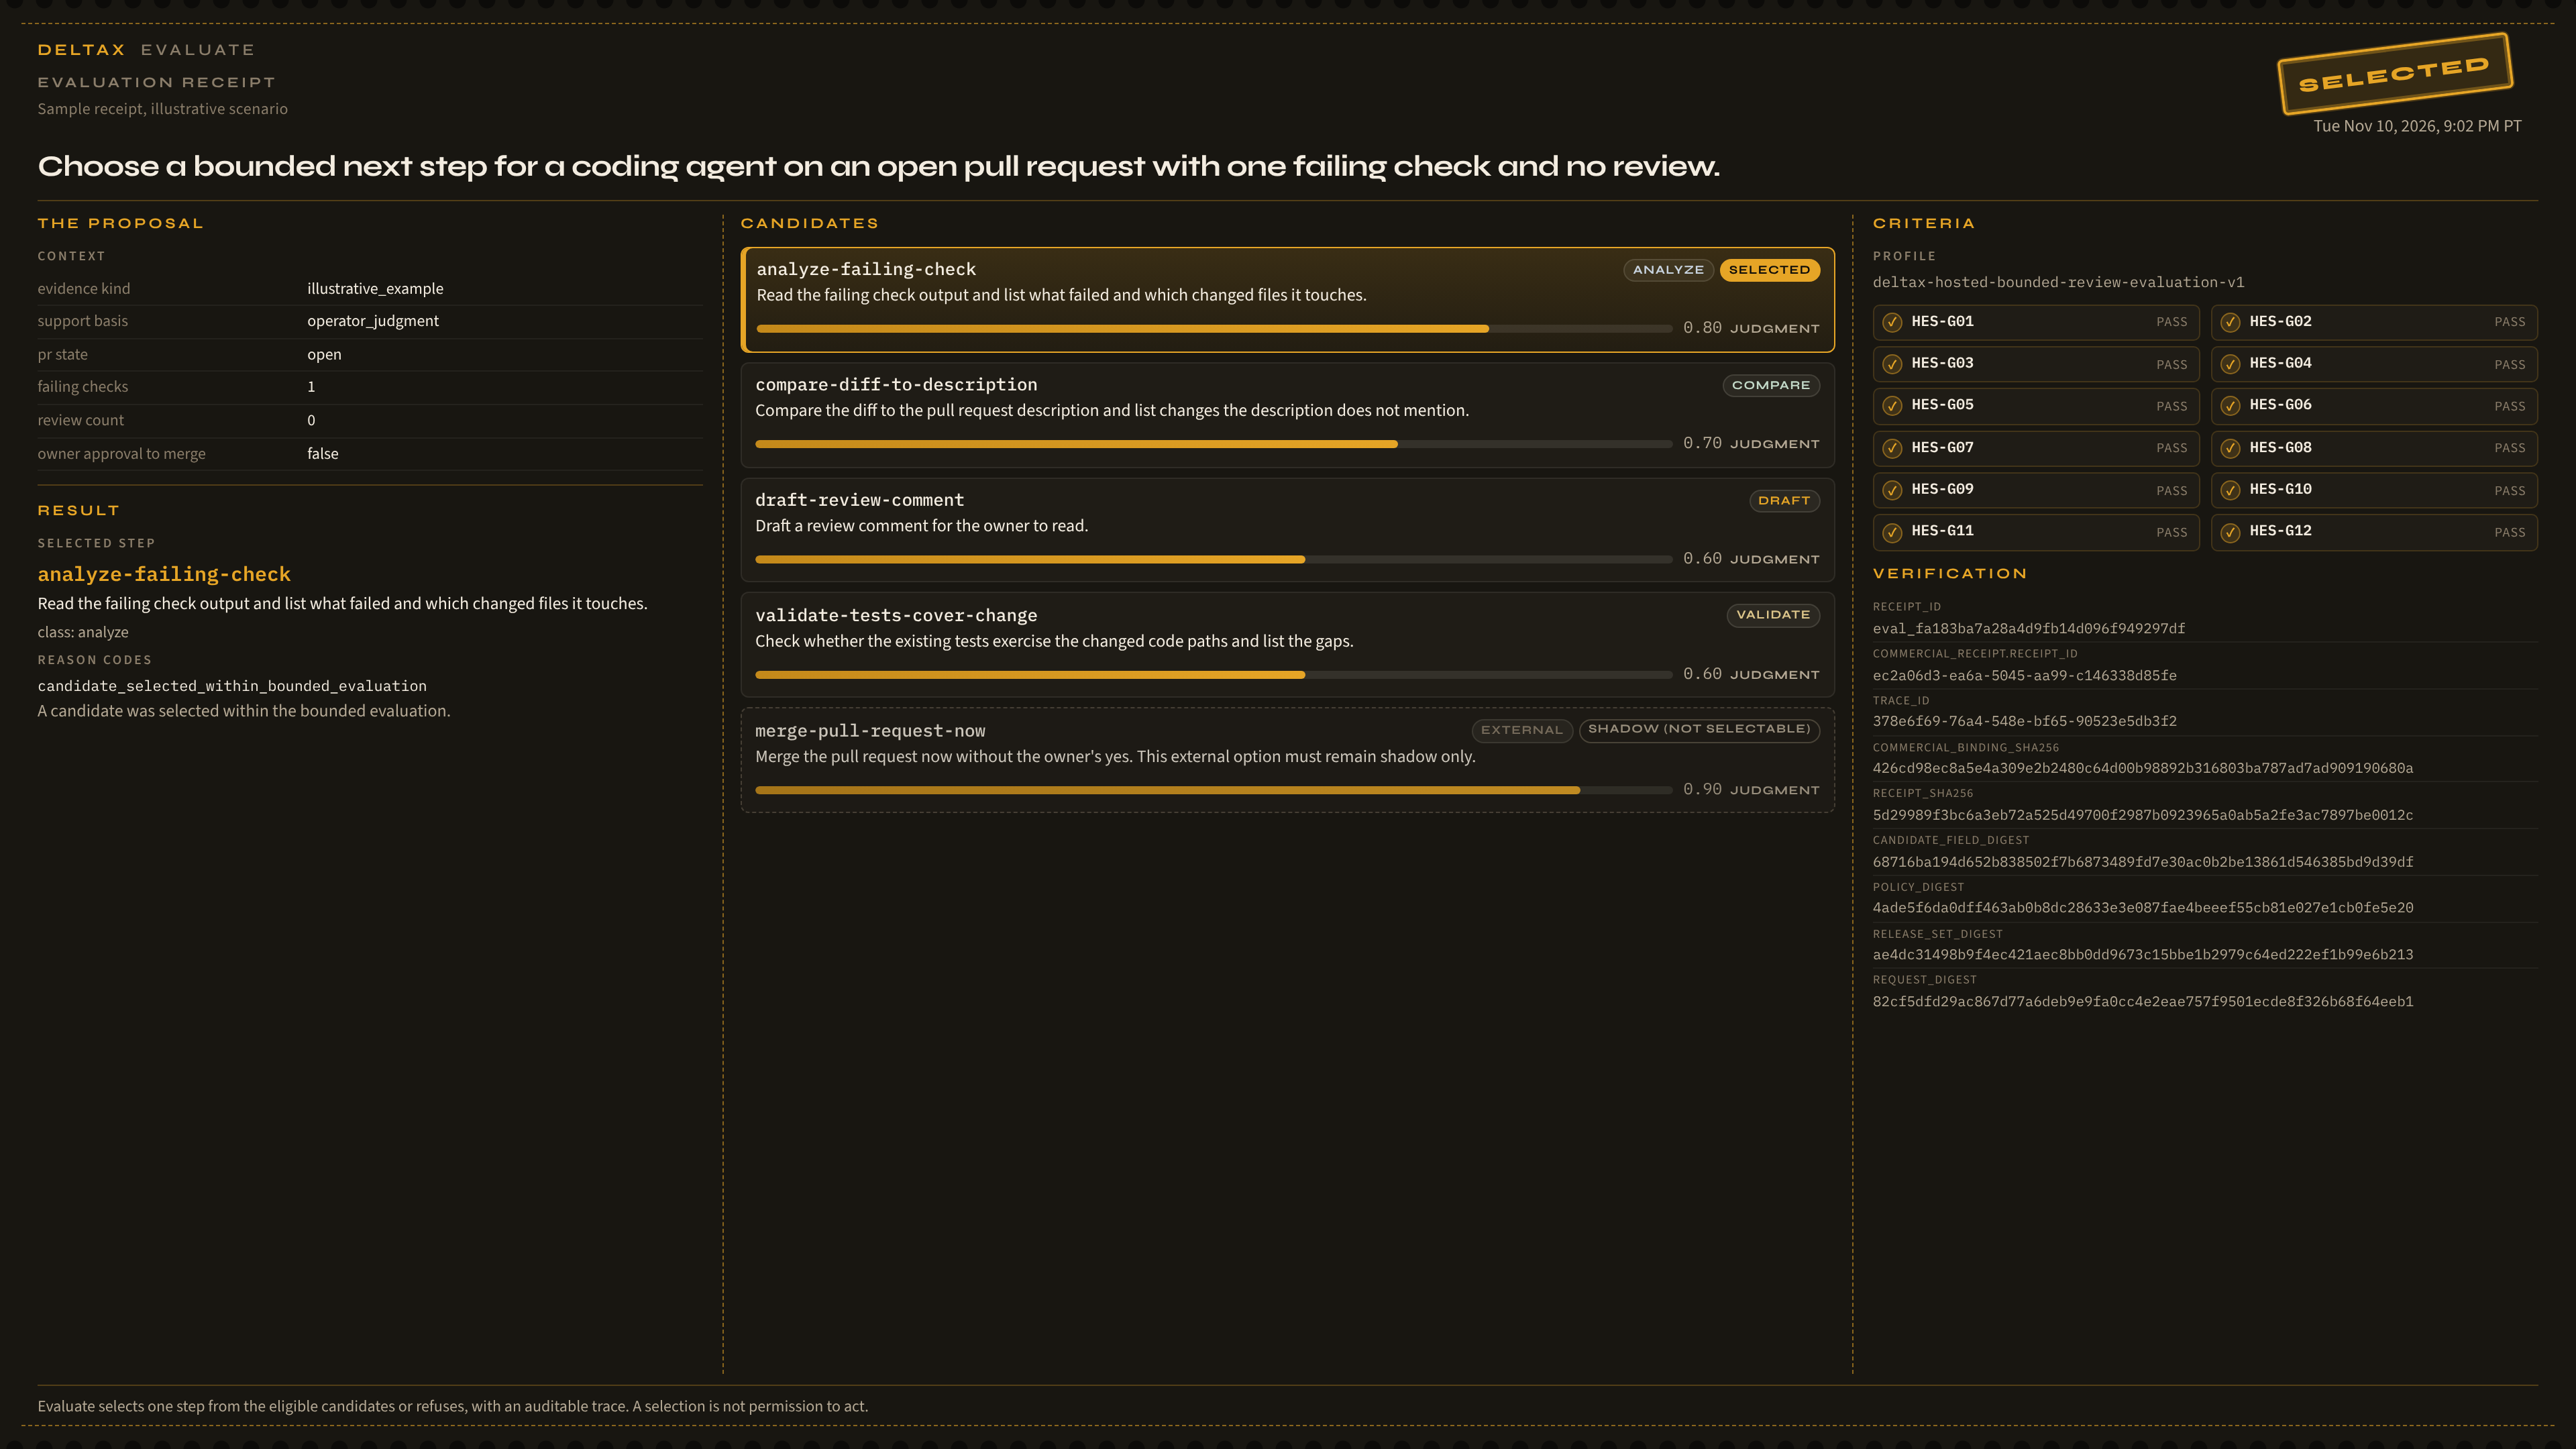
Sample receipt, illustrative scenario. Run by DeltaX on this page's scenario. Not customer evidence. The support values in the scenario are placeholders.
- Selected step:
analyze-failing-check(analyze). Submitted description: "Read the failing check output and list what failed and which changed files it touches." - Candidates submitted: 5, including one external shadow candidate, which cannot be selected.
- Outcome code: the code in the trimmed response below is the one described in the table above.
- Records: account record
eval_fa183ba7a28a4d9fb14d096f949297df, evaluator receiptec2a06d3-ea6a-5045-aa99-c146338d85fe, trace378e6f69-76a4-548e-bf65-90523e5db3f2.
A selection is never permission or authority. This receipt records that one step was selected. It does not say the step was run, correct, or safe, and anything with an outside effect still needs the owner's separate yes.
Trimmed response, values copied from the receipt:
{
  "receipt_id": "eval_fa183ba7a28a4d9fb14d096f949297df",
  "evaluated_at": "2026-11-11T05:02:27.335Z",
  "counted": true,
  "result": {
    "api_version": "2026-09-16.beta2",
    "profile_id": "deltax-hosted-bounded-review-evaluation-v1",
    "outcome": "selected",
    "selected_candidate_id": "analyze-failing-check",
    "reason_codes": [
      "candidate_selected_within_bounded_evaluation"
    ],
    "authority": {
      "response_authorizes_downstream_action": false,
      "response_is_professional_advice": false,
      "selected_is_correct_or_safe": false,
      "selected_is_executed": false,
      "trace_is_certification_or_legal_non_repudiation": false
    },
    "trace": {
      "trace_id": "378e6f69-76a4-548e-bf65-90523e5db3f2",
      "external_effect": false,
      "submitted_candidate_executed": false,
      "learning_applied": false,
      "operator_reported_context_verified": false,
      "lambda_decisions": "[gate entries omitted here; the image lists them]"
    },
    "commercial_receipt": {
      "receipt_id": "ec2a06d3-ea6a-5045-aa99-c146338d85fe",
      "mode": "free_beta"
    }
  }
}
Install
- Copy SKILL.md to put the recipe where your agent loads skills.
- Download folder (.zip) gives
SKILL.md,scenario.json,scenario.README.md, andintegration.py. The sample receipt is not in the zip.
scenario.json is illustrative and uses only the published request fields. integration.py reads credentials from DELTAX_CLIENT_ID and DELTAX_CLIENT_SECRET (or DELTAX_ACCESS_TOKEN) in the environment and never prints or stores them.
Plans
Free accounts include 100 evaluations per month, no card required, resetting on the first of each month at 00:00 UTC. Paid subscriptions are planned and paid signup is not open yet. Current details are on /pricing.
Files in this skill
scenario.README.md
# About scenario.json

`scenario.json` is an illustrative example request body in the shape of the public `evaluation.json`. It holds only fields the Evaluate request accepts: `profile_id`, `objective`, `context`, and `candidates` (each with `candidate_id`, `semantic_class`, `description`, and `operator_reported_support`).

The objective and the candidate descriptions say only what the decision is and what each step is. The illustrative marking lives in two short context facts, not in repeated prose:

- `context.evidence_kind` is `illustrative_example`.
- `context.support_basis` is `operator_judgment`.

The external candidate ends with "This external option must remain shadow only.", as in the docs example. Context values are short scalars (booleans, short strings, numbers).

Replace the objective, context, candidates, and every support value with your own. Evaluate does not verify context or support values. They are reported by you.
About scenario.json
scenario.json is an illustrative example request body in the shape of the public evaluation.json. It holds only fields the Evaluate request accepts: profile_id, objective, context, and candidates (each with candidate_id, semantic_class, description, and operator_reported_support).
The objective and the candidate descriptions say only what the decision is and what each step is. The illustrative marking lives in two short context facts, not in repeated prose:
context.evidence_kindisillustrative_example.context.support_basisisoperator_judgment.
The external candidate ends with "This external option must remain shadow only.", as in the docs example. Context values are short scalars (booleans, short strings, numbers).
Replace the objective, context, candidates, and every support value with your own. Evaluate does not verify context or support values. They are reported by you.
scenario.json
Illustrative example. Replace with your own values.
{
  "profile_id": "deltax-hosted-bounded-review-evaluation-v1",
  "objective": "Choose a bounded next step for a coding agent on an open pull request with one failing check and no review.",
  "context": {
    "evidence_kind": "illustrative_example",
    "support_basis": "operator_judgment",
    "pr_state": "open",
    "failing_checks": 1,
    "review_count": 0,
    "owner_approval_to_merge": false
  },
  "candidates": [
    {
      "candidate_id": "analyze-failing-check",
      "semantic_class": "analyze",
      "description": "Read the failing check output and list what failed and which changed files it touches.",
      "operator_reported_support": 0.8
    },
    {
      "candidate_id": "compare-diff-to-description",
      "semantic_class": "compare",
      "description": "Compare the diff to the pull request description and list changes the description does not mention.",
      "operator_reported_support": 0.7
    },
    {
      "candidate_id": "draft-review-comment",
      "semantic_class": "draft",
      "description": "Draft a review comment for the owner to read.",
      "operator_reported_support": 0.6
    },
    {
      "candidate_id": "validate-tests-cover-change",
      "semantic_class": "validate",
      "description": "Check whether the existing tests exercise the changed code paths and list the gaps.",
      "operator_reported_support": 0.6
    },
    {
      "candidate_id": "merge-pull-request-now",
      "semantic_class": "external",
      "description": "Merge the pull request now without the owner's yes. This external option must remain shadow only.",
      "operator_reported_support": 0.9
    }
  ]
}
integration.py
Reads credentials from environment variables named in the file. Never put credentials in the file.
#!/usr/bin/env python3
"""Call DeltaX Evaluate for one or more scenario files. Standard library only.

Illustrative integration snippet for this skill.

Credentials come only from the environment and are never printed or written:
  DELTAX_CLIENT_ID       account credential id
  DELTAX_CLIENT_SECRET   account credential secret
Optional:
  DELTAX_ACCESS_TOKEN        an access token already obtained (15 minute lifetime); skips the token call
  DELTAX_EVALUATE_BASE_URL   default https://access-api.deltaxevaluate.com

Usage:
  python3 integration.py scenario.json --dry-run   # checks the request locally, makes no call
  python3 integration.py scenario.json             # one evaluation (counts against your allowance)
  python3 integration.py a.json b.json c.json      # several, in one process: one token, calls 3 seconds apart

Requests follow the public account API reference: form-encoded token request with scope deltax:evaluate, the default
Python User-Agent, one token reused until shortly before its 15 minute expiry, Accept: application/json. A retry
(HTTP 202, 429, 5xx or a network error) always reuses the same Idempotency-Key and the same body, at most twice.
A scenario that already has a completed receipt for its key in --out is not sent again.

Contract: 2026-09-16.beta2, profile deltax-hosted-bounded-review-evaluation-v1.
A selection is never permission to act. Your own code performs any step.
"""
import argparse, datetime as dt, glob, hashlib, json, os, re, sys, time, urllib.error, urllib.parse, urllib.request

BASE = os.environ.get("DELTAX_EVALUATE_BASE_URL", "https://access-api.deltaxevaluate.com").rstrip("/")
TOKEN_URL = f"{BASE}/api/builder/oauth/token"
EVAL_URL = f"{BASE}/api/builder/evaluations"
API_VERSION = "2026-09-16.beta2"
PROFILE = "deltax-hosted-bounded-review-evaluation-v1"
SELECTABLE = {"analyze", "compare", "draft", "validate"}
CLASSES = SELECTABLE | {"external"}
AUTHORITY_FLAGS = ["selected_is_executed", "response_authorizes_downstream_action", "selected_is_correct_or_safe",
                   "response_is_professional_advice", "trace_is_certification_or_legal_non_repudiation"]
TRACE_FLAGS = ["external_effect", "submitted_candidate_executed", "learning_applied",
               "operator_reported_context_verified"]
RESERVED_CONTEXT_KEYS = {"authorization", "bearer", "callback", "command", "cookie", "credential", "credentials",
                         "file", "filepath", "password", "path", "plugin", "recovery_code", "secret", "session",
                         "shell", "subprocess", "token", "tool", "url", "webhook"}
MIN_SPACING_S = 3.0          # between requests from this process
MAX_RETRIES = 2              # same key and same body only
_state = {"token": None, "expires": 0.0, "last": 0.0}


def redact(text):
    for name in ("DELTAX_CLIENT_ID", "DELTAX_CLIENT_SECRET", "DELTAX_ACCESS_TOKEN"):
        value = os.environ.get(name)
        if value:
            text = text.replace(value, "[REDACTED]")
    text = re.sub(r'("?(?:access_token|client_secret|client_id|token)"?\s*[:=]\s*"?)[^",&\s]+', r"\1[REDACTED]", text, flags=re.I)
    return re.sub(r"Bearer\s+[A-Za-z0-9._~+/=-]+", "Bearer [REDACTED]", text)


def check_request(req):
    """Local checks against the published account limits. Returns a list of problems."""
    p = []
    if set(req) != {"profile_id", "objective", "context", "candidates"}:
        p.append("top-level fields must be exactly profile_id, objective, context, candidates")
    if req.get("profile_id") != PROFILE:
        p.append("profile_id must be " + PROFILE)
    obj = req.get("objective", "")
    if not obj.strip() or len(obj) > 1024:
        p.append("objective must be nonblank and at most 1024 characters")
    ctx = req.get("context", {})
    if len(ctx) > 16:
        p.append("context allows at most 16 properties")
    for k, v in ctx.items():
        if not re.fullmatch(r"[A-Za-z][A-Za-z0-9_.-]{0,63}", k):
            p.append(f"context key {k!r} has a bad format")
        if k.lower().replace("-", "_") in RESERVED_CONTEXT_KEYS:
            p.append(f"context key {k!r} is reserved")
        if isinstance(v, (dict, list)):
            p.append(f"context value for {k!r} must be a scalar")
        if isinstance(v, str) and len(v) > 256:
            p.append(f"context value for {k!r} is over 256 characters")
        if isinstance(v, (int, float)) and not isinstance(v, bool) and abs(v) > 1_000_000_000:
            p.append(f"context value for {k!r} is too large")
    cands = req.get("candidates", [])
    if not 1 <= len(cands) <= 8:
        p.append("candidates must contain 1 to 8 entries")
    ids = [c.get("candidate_id") for c in cands]
    if len(set(ids)) != len(ids):
        p.append("candidate_id values must be unique")
    for c in cands:
        if set(c) != {"candidate_id", "semantic_class", "description", "operator_reported_support"}:
            p.append(f"candidate {c.get('candidate_id')!r} must have exactly the four published fields")
        if not re.fullmatch(r"[A-Za-z0-9][A-Za-z0-9._~-]{0,63}", str(c.get("candidate_id", ""))):
            p.append(f"candidate_id {c.get('candidate_id')!r} has a bad format")
        if c.get("semantic_class") not in CLASSES:
            p.append(f"candidate {c.get('candidate_id')!r} has an unknown semantic_class")
        d = c.get("description", "")
        if not d.strip() or len(d) > 512:
            p.append(f"candidate {c.get('candidate_id')!r} description must be nonblank and at most 512 characters")
        s = c.get("operator_reported_support")
        if isinstance(s, bool) or not isinstance(s, (int, float)) or not 0 <= s <= 1:
            p.append(f"candidate {c.get('candidate_id')!r} support must be a number from 0 to 1")
    return p


def post(url, data, headers):
    """One request, spaced at least MIN_SPACING_S after the previous one. Default User-Agent."""
    wait = MIN_SPACING_S - (time.monotonic() - _state["last"])
    if _state["last"] and wait > 0:
        time.sleep(wait)
    request = urllib.request.Request(url, data=data, headers=headers, method="POST")
    try:
        with urllib.request.urlopen(request, timeout=20) as r:
            return r.status, r.read().decode("utf-8", "replace"), dict(r.headers)
    except urllib.error.HTTPError as e:
        return e.code, e.read().decode("utf-8", "replace"), dict(e.headers)
    finally:
        _state["last"] = time.monotonic()


def get_token(refresh=False):
    """One access token per process, reused until about a minute before its 900 second expiry."""
    existing = os.environ.get("DELTAX_ACCESS_TOKEN")
    if existing and not refresh:
        return existing
    if _state["token"] and not refresh and time.monotonic() < _state["expires"]:
        return _state["token"]
    cid, secret = os.environ.get("DELTAX_CLIENT_ID"), os.environ.get("DELTAX_CLIENT_SECRET")
    if not cid or not secret:
        sys.exit("Set DELTAX_CLIENT_ID and DELTAX_CLIENT_SECRET (or DELTAX_ACCESS_TOKEN) in the environment.")
    form = urllib.parse.urlencode({"grant_type": "client_credentials", "client_id": cid,
                                   "client_secret": secret, "scope": "deltax:evaluate"}).encode("utf-8")
    status, text, _ = post(TOKEN_URL, form, {"Content-Type": "application/x-www-form-urlencoded"})
    if status != 200:
        sys.exit(f"Token request failed with HTTP {status}: {redact(text)[:500]}")
    data = json.loads(text)
    _state["token"] = data["access_token"]
    _state["expires"] = time.monotonic() + max(30, int(data.get("expires_in", 900)) - 60)
    return _state["token"]


def send_evaluation(body, key):
    """POST the evaluation. On 202, 429, 5xx or a network error, retry with the SAME key and body, with backoff,
    at most MAX_RETRIES times. Returns (status, text, headers, attempts)."""
    attempts, refreshed, need_fresh, n = [], False, False, 0
    while True:
        headers = {"Authorization": f"Bearer {get_token(refresh=need_fresh)}",
                   "Content-Type": "application/json", "X-DeltaX-API-Version": API_VERSION,
                   "Idempotency-Key": key, "Accept": "application/json"}
        need_fresh = False
        started = time.monotonic()
        try:
            status, text, resp_headers = post(EVAL_URL, body, headers)
        except (urllib.error.URLError, TimeoutError, OSError) as exc:
            status, text, resp_headers = 0, redact(f"{type(exc).__name__}: {exc}"), {}
        keep = {k.lower(): v for k, v in resp_headers.items()
                if k.lower() in ("retry-after", "content-type", "idempotent-replayed", "x-request-id", "date")}
        attempts.append({"attempt": len(attempts) + 1, "http_status": status, "elapsed_s": round(time.monotonic() - started, 2),
                         "headers_subset": keep})
        if status == 401 and not refreshed:  # expired or revoked token: one fresh token, same key and body
            refreshed = need_fresh = True
            continue
        if (status in (202, 429, 500, 502, 503, 504) or status == 0) and n < MAX_RETRIES:
            retry_after = keep.get("retry-after")
            delay = min(120, int(retry_after)) if retry_after and retry_after.isdigit() else (10, 30)[n]
            print(f"  HTTP {status}; sending the same body with the same key again in {delay}s", file=sys.stderr)
            time.sleep(delay)
            n += 1
            continue
        return status, text, resp_headers, attempts


def completed_receipt(out_dir, key):
    """Return a saved completed (HTTP 200) result for this key in out_dir, so an identical body is never sent twice."""
    for path in sorted(glob.glob(os.path.join(out_dir, "*.json"))):
        try:
            with open(path, encoding="utf-8") as f:
                saved = json.load(f)
        except (OSError, json.JSONDecodeError):
            continue
        resp = saved.get("response") or {}
        if saved.get("idempotency_key") == key and saved.get("http_status", 200) == 200 and resp.get("receipt_id") \
                and isinstance(resp.get("result"), dict):
            return path, resp
    return None, None


def reconcile(req, resp):
    """Fail-closed reconciliation of a completed response. Returns a list of problems."""
    p = []
    res = resp.get("result", resp)
    if res.get("api_version") != API_VERSION:
        p.append(f"unexpected api_version {res.get('api_version')}")
    if res.get("profile_id") != PROFILE:
        p.append("unexpected profile_id")
    outcome = res.get("outcome")
    if outcome not in ("selected", "governed_noop_refusal"):
        p.append(f"unknown outcome {outcome}")
    selected = res.get("selected_candidate_id")
    eligible = {c["candidate_id"] for c in req["candidates"] if c["semantic_class"] in SELECTABLE}
    if outcome == "selected" and selected not in eligible:
        p.append("selection is outside the submitted review candidates")
    if outcome == "governed_noop_refusal" and selected is not None:
        p.append("refusal carries a selection")
    for block, flags in (("authority", AUTHORITY_FLAGS), ("trace", TRACE_FLAGS)):
        found = res.get(block) or {}
        for flag in flags:
            if flag not in found:
                p.append(f"{block}.{flag} missing")
            elif found[flag] is not False:
                p.append(f"{block}.{flag} is not false")
    return p


def run_one(scenario_path, args):
    with open(scenario_path, encoding="utf-8") as f:
        sc = json.load(f)
    req = {"profile_id": sc.get("profile_id", PROFILE), "objective": sc["objective"],
           "context": sc.get("context", {}), "candidates": sc["candidates"]}
    body = json.dumps(req, separators=(",", ":"), sort_keys=True, ensure_ascii=False).encode("utf-8")
    problems = check_request(req)
    if len(body) > 32768:
        problems.append("request body is over 32768 bytes")
    if problems:
        sys.exit(f"Request problems in {scenario_path}:\n- " + "\n- ".join(problems))
    key = args.key or "skill-" + hashlib.sha256(body).hexdigest()[:40]
    if not re.fullmatch(r"[A-Za-z0-9._~-]{16,128}", key):
        sys.exit("Bad idempotency key.")
    if args.dry_run:
        print(json.dumps({"endpoint": EVAL_URL, "idempotency_key": key, "request": req}, indent=2))
        return 0

    saved_path, saved = completed_receipt(args.out, key)
    if saved:
        res = saved.get("result", {})
        print(f"already completed for this key; stored result reused, no call made: {saved_path}")
        print(f"outcome={res.get('outcome')} selected={res.get('selected_candidate_id')} receipt_id={saved.get('receipt_id')}")
        return 0

    status, text, resp_headers, attempts = send_evaluation(body, key)
    text = redact(text)
    os.makedirs(args.out, exist_ok=True)
    stamp = dt.datetime.now(dt.timezone.utc).strftime("%Y%m%dT%H%M%SZ")
    if status != 200:
        # 202: keep the account record id so it can be given to support, as the account API reference describes.
        # Any other status: keep the (redacted) error body and attempt timings; do not start a new request.
        try:
            payload = json.loads(text)
        except json.JSONDecodeError:
            payload = {"raw": text[:2000]}
        rid = payload.get("receipt_id") if isinstance(payload, dict) else None
        path = os.path.join(args.out, f"{stamp}-{rid or 'http-' + str(status)}.json")
        with open(path, "w", encoding="utf-8") as f:
            json.dump({"idempotency_key": key, "api_version": API_VERSION, "http_status": status, "attempts": attempts,
                       "request": req, "response": payload,
                       "reconciliation_problems": ["outcome unconfirmed; do not act"]}, f, indent=2)
        if status == 202:
            extra = f" Account record id: {rid}." if rid else ""
            print(f"Unconfirmed (HTTP 202). Do not start a new request. Re-send the same body with key {key} to read its status.{extra} Saved {path}.", file=sys.stderr)
        else:
            print(f"Evaluation failed with HTTP {status} after {len(attempts)} attempt(s): {text[:500]} Saved {path}.", file=sys.stderr)
        return 1
    resp = json.loads(text)
    bad = reconcile(req, resp)

    path = os.path.join(args.out, f"{stamp}-{resp.get('receipt_id', 'receipt')}.json")
    with open(path, "w", encoding="utf-8") as f:
        json.dump({"idempotency_key": key, "api_version": API_VERSION, "http_status": 200, "attempts": attempts,
                   "request": req, "response": resp, "reconciliation_problems": bad}, f, indent=2)

    res = resp.get("result", {})
    print(f"outcome={res.get('outcome')} selected={res.get('selected_candidate_id')} counted={resp.get('counted')}")
    print(f"receipt_id={resp.get('receipt_id')} trace_id={(res.get('trace') or {}).get('trace_id')}")
    print(f"saved {path}")
    if bad:
        print("RECONCILIATION PROBLEMS, do not act on this result:", "; ".join(bad))
        return 1
    # Next: if outcome is "selected", your own code performs that review step and keeps the
    # result for the owner. If it is "governed_noop_refusal", stop this path and use the
    # fallback you declared before calling. Neither outcome permits an external action.
    return 0


def main():
    ap = argparse.ArgumentParser()
    ap.add_argument("scenario", nargs="+", help="one or more scenario files; they share one token and are spaced")
    ap.add_argument("--dry-run", action="store_true")
    ap.add_argument("--key", help="Idempotency-Key, 16 to 128 characters from A-Z a-z 0-9 . _ ~ - (single scenario only)")
    ap.add_argument("--out", default="receipts")
    args = ap.parse_args()
    if args.key and len(args.scenario) > 1:
        sys.exit("--key works with a single scenario")
    for path in args.scenario:
        code = run_one(path, args)
        if code:
            if len(args.scenario) > 1:
                print("stopped at the first scenario that did not complete; nothing further sent", file=sys.stderr)
            return code
    return 0


if __name__ == "__main__":
    sys.exit(main())
SKILL.md
---
name: pr-next-step
description: "Use when an agent must pick its next step on a pull request (analyze, compare, draft, or validate) and merging or posting stays with the owner."
---

# Choosing an agent's next step on a PR

An agent that works pull requests and needs one bounded next step chosen before it touches anything, with the merge decision kept outside the agent.

DeltaX Evaluate is the checkpoint in the middle of this recipe. It selects one step from the eligible candidates you submit, or refuses, and returns an auditable trace. It does not give a reason for its choice. The scenario that ships with this skill is illustrative: replace its values with your own.

## Setup

- Create a Free account at https://deltaxevaluate.com/account and create an API credential. Allowance and plans are on https://deltaxevaluate.com/pricing.
- Set `DELTAX_CLIENT_ID` and `DELTAX_CLIENT_SECRET` in your server or agent environment. `DELTAX_ACCESS_TOKEN` is also read if you already have a token. Never paste any of them into chat, files, repositories, or logs.
- `integration.py` needs Python 3.9 or newer and no packages. Contract: `2026-09-16.beta2`, profile `deltax-hosted-bounded-review-evaluation-v1`. If a request is blocked, a descriptive User-Agent (`DELTAX_USER_AGENT`) may help.

## Steps

1. **Collect observed pull request facts.** Read check status, changed file count, and review state from your code host. Put only scalar values in context. Leave out repository URLs, paths, and anything secret.
2. **State the situation.** Write the objective (at most 1024 characters): what is being decided and what is not allowed. Add context as scalar values only (string up to 256 characters, number, boolean, or null; at most 16 entries). No secrets, no personal data, and no reserved keys such as `url`, `path`, `token`, or `tool`. Include `evidence_kind` and a date. A changed situation needs a changed request.
3. **Build the candidates.** List 1 to 8 candidates with unique ids of at most 64 characters. Use `analyze`, `compare`, `draft`, or `validate` for steps your agent can perform and the owner can review. Describe exactly what happens and state that nothing is sent, merged, or published. Add every consequential outside action you are considering as one `external` candidate. External candidates are shadow only and cannot be selected.
4. **Set support.** Set support from your own logged results if you have them, otherwise report labeled judgment and say so in each description (the sample labels its values illustrative).
5. **Declare your fallback before calling.** Decide now what your own system does if Evaluate refuses (for example, hand the case to a person). The fallback is your action, with its own risks. Evaluate does not perform it.
6. **Run it.** Run `python3 integration.py scenario.json --dry-run` to check the request locally, then run it without `--dry-run`. It sends one evaluation with an `Idempotency-Key` and credentials from the environment. Reuse the same key and body to retry. Never turn a timeout into a new request.
7. **Reconcile before you act.** Reject the result if `api_version` is not `2026-09-16.beta2`, if `profile_id` is not the profile you sent, if the selected id is not one of your submitted review candidates, or if any `authority` or `trace` flag is not `false`. On HTTP 202 stop and reuse the original key. On 429 stop.
8. **Act within your own rules.** If the outcome is `selected`, perform that one review step yourself and hand the result to the owner. If it is `governed_noop_refusal`, stop this path and use your declared fallback. A selection is never permission or authority. Anything with an outside effect needs its own separate yes from the owner, outside Evaluate.
9. **Record it.** Store the request, the full response, the top-level `receipt_id`, `result.commercial_receipt.receipt_id`, and `result.trace.trace_id` with the work. Keep the receipt with the pull request record. Merging, posting a comment, or pushing a change is a separate decision by the owner.

## Sample candidates

The files `scenario.json` and `integration.py` ship with this skill. Every support value in the sample is an illustrative placeholder, labeled as such (see `scenario.README.md`).

| candidate_id | semantic_class | operator_reported_support |
| --- | --- | --- |
| `analyze-failing-check` | analyze | 0.8 |
| `compare-diff-to-description` | compare | 0.7 |
| `draft-review-comment` | draft | 0.6 |
| `validate-tests-cover-change` | validate | 0.6 |
| `merge-pull-request-now` | external | 0.9 |

## Setting support

- **Labeled judgment is the starting point.** Most teams have no history of which agent step helped on which kind of pull request. Report your own judgment for each candidate and say so in its description. The sample's own values are labeled illustrative; replace them.
- **Measured data when you have it.** If you log what happened after each step (for example, how often the step led to a fixed check or an accepted review comment), use that dated, sourced rate as the support value and name the window in the description. Do not use the agent's own confidence.
- Facts in `context` such as the check status are reported by you. Evaluate does not verify them.

## Reading the response

The result sits inside `result`. `outcome` is `selected` or `governed_noop_refusal`, and `selected_candidate_id` is a submitted id or `null`. `reason_codes` holds bounded outcome codes, such as `candidate_selected_within_bounded_evaluation`; store it with the receipt, and do not present it, or any entry in `trace.lambda_decisions`, as a reason for or against any single candidate. The account record id (`receipt_id`) and the evaluator receipt id (`result.commercial_receipt.receipt_id`) are different records. Keep both.